Guidance
ARR Reviewer Guidelines
On this page
Important changes!
These guidelines were updated for October’26 review cycle.
🆕 Reviewer qualifications and service requirements
There are two types of reviewers in ARR: the designated service contributors, which come nominated by the submission authors, and volunteer reviewers.
- Designated service contributors are part of the sustainable revieweing policy. They are nominated by authors at submission time to support specific submissions, and must confirm their participation through contributor form
- Volunteer reviewers are part of standing service pool, where participation is voluntary. They receive service invitations and may accept them when convenient. More details here.
Both volunteers and designated contributors are supposed to be qualified. The main difference is in the process through which they sign up, and expectations for emergency declarations (designated contributors must provide a qualified and willing replacement). Volunteer reviewers have more freedom in selecting their load (see here). If a volunteer reviewer becomes a designated contributor in a specific review cycle via author nomination, their preferences as a volunteer are overridden by designated contributor settings.
ARR service rewards and penalties
Great reviewers & chairs. Starting from May 2025, ACL implements the awards policy for reviewers & chairs. In short, the area chairs or senior area chairs may nominate the great reviewers, and senior chairs may also nominate area chairs who perform great service. The nominees will then receive more recognition during the ACL conferences (public lists on conference websites, special stickers for conference badges, more visibility in the program). They may also win a free virtual registration for an ACL event as an attendee (i.e. an event for which they would probably not have financial support of their organization).
Irresponsible reviewers and chairs. The ‘highly irresponsible’ reviewers or chairs will have their work desk-rejected from the current cycle, and they will be disqualified from ARR service for the following ARR cycle. This means that they would not be ‘sponsor’ their own submissions as designated contributors, and their work will go in the lottery for spare capacity, unless someone else provides service for them. Note that authors may assist chairs in identifying poor reviews by submitting review issue reports, referring to specific sections of these guidelines (I1-I12). Area chairs may directly flag specific problematic reviews.
What are the confidentiality and anonymity rules for reviewing?
All the information about submissions and reviews that you receive as part of your assignment is confidential. This entails the following:
- If you participate in discussions of peer review on social media, please make sure that your comments/examples are general enough that no submissions can be identified, and the authors cannot identify you. Do not refer to individual papers.
- You should not submit any confidential information to third party services that may retain and use that information. In particular that includes some popular generative AI services. See the section on generative AI assistance in reviewing.
What about review data for research? After the review process is completed, anonymized review data can be provided to the research community, given the consent of the willing reviewers and authors. ARR implemented a framework for proactive data collection from the willing reviewers and authors agreeing to contribute it. We hope that you would consider opting in. This is done in the form where you set your availability for review cycles. The more data we have, the more we can do as NLP experts to improve peer review.
What about the author anonymity? While ACL has replaced the embargo period with other measures to incentivize anonymity, the reviewing guidelines are as follows:
To preserve the merits of double-blind review, reviewers for *ACL conferences and TACL should be instructed not to actively try to discover the identity of the authors and not to let any suspicion or knowledge of author identity affect their judgment of the paper. This should not prevent them from searching for related work, but they should take special care and postpone such searches until after they have read the paper completely and formed an initial impression of it. If a reviewer nevertheless uncovers the identity of the authors (or believes they can identify the authors for other reasons), they should inform the area chair or action editor (but not other reviewers) so that this information can be taken into account when making the final acceptance decision.
Hence, we ask for the following workflow: (1) read the paper and get the first impression, (2) search for related work, not deliberately trying to find that particular submission. If you become aware or can guess the authors’ identity, you should disclose that in the ARR review form, which contains questions about the reviewers’ knowledge of author identity. In some cases it is appropriate to ask for a reassignment.
✅ TASK 1. Allocate time in your calendar for both reviewing and updates in author response period
In the beginning of review cycle, there will be a kick-off email from OpenReview listing the important dates for this cycle. Usually the email subject is [ACL RR-(MONTH)] Reviewing period starts … (DATE).
Please block the time in your calendar for (1) checking the assignments, (2) working on the reviews, (3) submitting them on time, and (4) updating them after author response, e.g. if the authors identified some major misunderstandings on your side.
✅ TASK 2. Assignment check
Expertise and COI check: can you review these papers?
As soon as you get an assignment, skim the paper to check whether this is something that you are qualified to review. The assignments are made based on a semi-automatic process, and, even with careful checks by the area chair, you may feel like you are not qualified to review a given submission.
Yet, even in the best-case scenario, the matches will not always be perfect. For very novel work or atypical papers, it is inherently difficult to find available qualified reviewers. The possibility of a very close match also depends on the set of people in the reviewing pool, therefore increasing the chances of a good match for the large, popular subfields. And even large subfields may experience a lack of well-matching reviewers when they are actively growing. Moreover, sometimes a less obvious match may also be a conscious decision on the part of the AC, e.g., to collect reviewers from different perspectives when the paper is interdisciplinary, or when it focuses on less popular topics and languages.
So, the bad news is that, realistically, you will sometimes be asked to review papers that are a bit outside of your own subfield. That is ok as long as you are sufficiently familiar with the core methodology and the kinds of arguments that are typically made in our field’s papers. If your expertise does not cover certain aspects of the submission, your review should specify that, and you will also be able to indicate your confidence score in the ARR form.
The good news is that the less-than-perfect matches also have upsides: you get to expand your repertoire, the authors get feedback on what needs more clarification/explanation, and NLP in general gets more intellectual exchange between subfields.
The second thing to check is whether you know or can guess who the authors are. Ideally, ARR peer review should be fully anonymous. The problem with implicit social biases is that they are unconscious; we may be 100% sure that we do not think worse of a paper just because it is written by someone from a group minoritized in computing research and that we are not predisposed to like papers coming from famous labs, but we cannot really trust our conscious selves. If you happen to know who the authors are from personal communication, social media or talks, the review form will contain a field for you to indicate whether you know who the authors are. If you believe that some case is particularly bad and may severely compromise your judgement (e.g. because of a conflict of interest (COI): you know the authors personally, have or will work with them, etc.), please ask your AC for re-assignment if possible.
If you feel that you are qualified to review some aspects of the paper but not others (e.g. experimental results but not the formal proofs), please state in the review if you did not check some major parts, such as proofs. This information is helpful for the AC to tell what aspects of the paper were not reviewed.
The third check is on academic conflicts of interest. If the submission looks like something that is very close to your own work about to be submitted, it is best to recuse yourself.
If you feel that this submission is a very bad match on one of these criteria, please contact your AC.
🆕 Should these papers be reviewed or desk-rejected?
As you are likely aware, major conferences currently struggle with an influx of submissions, not all of which merits full review. At ARR, first the papers are checked by ACs, and we try to remove as many problematic papers as possible before they are seen by you. But it is possible that some are still in your batch, and so we provide you with the possibility to report them through a checklist form similar to AC checklist. Especially if you can see that some of your papers do not have a completed AC checklist, please complete yours. To submit your checklist, open the page of the submission you were assigned, and click on the ‘reviewer checklist’ button.
Doing checklists early could reduce your number of assignments to fully review, but only if you do this early: if the motion to desk reject was filed less than a week to submission deadline, you are still expected to perform the reviews, under any non-compliance sanctions that may apply to your service role. At this stage you are not reading the paper in full yet. The checklist is an opportunity to proactively recommend desk rejections for submissions that would likely receive very low scores, or would have to be desk rejected for technical issues.
The technical issues (formatting, deanonymization, salami slicing, responsible checklist issues, problematic references) only need to be reported, and then the case will be handled by the editors.
Two kinds of issues need more discussion: submissions that are too poor quality to proceed further, and submissions that are out of scope for the *CL conferences. Here we ask the committee for the paper to both report these issues and discuss between yourselves to provide your reasoning and see if you agree. When a chair or a reviewer files a checklist item with one of these issues, a notification will be triggered for everyone participating in the forum. SACs in particular must indicate their stance, and where they confirm that desk reject should be considered - ARR EiCs and conference PCs will make the final decision.
Please respond to the checklist message in the forum, indicating whether you support the motion to desk reject and why, using the new ‘checklist comment’ button on the checklist that initially proposed desk rejection. It is called ‘area chair checklist comment’ for ACs, and ‘reviewer checklist comment’ for reviewers.

Overall level. For low-quality submissions, this step focuses on the obvious cases. Unfortunately, sometimes this is hard to tell without a full careful read, which you are not expected to perform. But if you have an obvious case, it is possible to quickly report it at this stage. Submissions with too low overall level may not necessarily be generated, but clearly not ready to be ready for consideration for acceptance at a top-tier conference. Reviewer feedback is not meant as replacement for training that the authors should receive in their programs. Please use this option for submissions that would likely end up with meta-review scores 1.5 or below (‘resubmit after 1 cycle’ with substantial revisions, or ‘do not resubmit’).
Another big problem is out-of-scope submissions. Unfortunately, many authors appear to mistake CL conferences for generic machine learning venues. We welcome interdisciplinarity, but we still expect that the primary contribution of ARR submissions is to the field of NLP, and not mainly the field from which the interdisciplinary work originates. One rule of thumb is that even interdisciplinary contributions should have a substantial proportion of references from the host community (CL).
Depending on your track, the following may also be relevant for out-of-scope submissions:
- Work on multimodality, coding models, or symbolic reasoning should still have the human language component as a key target of modeling/analysis. Simply using LLMs for solving a non-NLP problem is not enough. Such work should go to generic ML conferences. For example, rather than code generation itself, the focus could be on the ‘translation’ from natural language formulation into code.
- Work on ML, efficiency, security, agents, applications, interpretability should clearly make a contribution to processing of human language. This means that the utility of any proposed methods should be shown in natural language evaluations. Where the evaluations are language-based but purely synthetic without a good justification (e.g. in medical data, psycholinguistic stimuli), this is not by itself out of scope, but may merit a low overall assessment.
These are only rough heuristics, you have full discretion for when they do not apply.
I’ve seen this paper submitted elsewhere, should I report it? As a rule, submissions to ARR are not supposed to be under review anywhere else (unless specific exceptions are made due to notification date overlaps). All submissions are pre-checked by chairs for double submissions to concurrent conferences. If we missed it, and you happen to have seen the same paper in a concurrent review cycle elsewhere — please let us know.
Should I still review a submission if it has been suggested for desk rejection? You should still plan to complete the review for that paper, until the desk rejection is confirmed by the chairs. The earlier the desk rejection is suggested, the more time the chairs will have for this, and the higher the chance that you will not have to review this submission.
What if I already submitted the checklist and then found a serious problem? If you already submitted a checklist, and then found a problem that should have been reported there - it is possible to edit the checklist you already submitted.
✅ TASK 3. Write a strong review
Check whether the paper is a resubmission: if so, it should have a link in the “Previous URL” field in the metadata, and it should point to the previous submission. If that’s the case, refer to the section on resubmissions.
1. Adjust your expectations I6 I7
One reading strategy that seems to be often used, but not well suited for peer review is commenting/critiquing during the first (and only) read. The problem is that any criticism is done from a certain perspective. If you don’t adjust it, you are relying on your default perspective, which is likely formed by a ‘prototype’ paper in your own subfield. If your prototype is a long paper with experimental results, and you get something else, you might be biased against it for just not being the type of work that you expected. Hence, please read the paper at least twice: skimming and in-depth reading.
1. Skim-reading: adjusting your expectations.
- What is the research question and what was done to answer it? Will the answer advance the field? Do NOT look at the results yet. Hindsight bias may make things seem obvious in retrospect, and confirmation bias may make you dismiss evidence that contradicts your beliefs. Remember that the goal of research is to contribute new knowledge.
- If the methodology and the type of contribution in scope of the CFP? NLP is an interdisciplinary field, and we might learn from papers that don’t do the same thing we do. E.g. there was a case when a *CL reviewer criticized a resource paper as follows: ‘the paper is mostly a description of the corpus and its collection and contains little scientific contribution’. This is particularly unfortunate when the modeling work has far outpaced the development of theory and documentation. Furthermore, given the sad state of replicability of NLP experiments, even in published papers, reimplementations and systematic analyses of prior work should be encouraged.
- Is the claim appropriately scoped? This applies to all papers, but especially to the short ones. They may present a proof of concept, an interesting finding, a convincing point, a negative result, and they are very easy to criticize with “it would be nice/more complete to add X”. Such a criticism can be made for most papers. It is only valid if the argument that is being made depends on X.
In-depth reading. This is where you evaluate the evidence that is presented for its technical soundness, proof validity, sound argumentation, novelty, etc. How to do this best depends on the type of paper and your workflow.
Should I check for related work? Please do that carefully, and only after you’ve drafted your review. Many papers have non-anonymous preprints, and you may accidentally discover the identity of authors, which would open you up to social biases. Do NOT deliberately search for the preprinted version of the paper you were assigned. Papers may reference unpublished related work, performed by an overlapping set of authors; in that case, the authors were instructed to discuss it in the related work, and include an anonymized copy in the ‘data’ attachment field.
Do I have to read the appendices? The paper should be readable by itself, and any details important for understanding the key aspects of the work should be in the paper rather than in appendices. The authors may provide supplementary material with extra experiments, implementation details, examples, code, or data, but you are not required to consider such material. However, if you happen to have a question about supplementary experiments, methodological details etc., and the paper explicitly refers to the appendix for more information about that specific issue — looking it up would save everybody’s time. Often, we see author rebuttals that simply refer the reviewer to the appendix for exactly the thing they asked for. At the same time, if something has been relegated to the appendix that you, as a reviewer, believe belongs in the main paper, this is a reasonable suggestion to make to the authors to improve the paper (but not a serious weakness as such modifications are usually simple).
2. Be specific I1
If you would like to flag any issues, it should be specific and ideally understandable to the chairs without reading the full paper. Let us consider a few examples.
| ❎ Instead of: | ✅ Use: |
| The paper is missing relevant references | The paper is missing references XYZ |
| X is not clear | Y and Z are missing from the description of X. |
| The formulation of X is wrong | The formulation of X misses the factor Y |
| The contribution is not novel | Highly similar work X and Y has been published 3+ months prior to submission deadline |
| The paper is missing recent baselines | The proposed method should be compared against recent methods X, Y and Z (see H14 below for requesting comparisons to 'closed' systems) |
| X was done in the way Y | X was done in the way Y which has the disadvantage Z |
| The algorithm's interaction with dataset is problematic | It's possible that when using the decoding (line 723) on the dataset 3 (line 512), there might not be enough training data to rely on the n-best list. |
| [If reasonably well-known entities are discussed] \ It’s possible that when using the decoding from Smith and Eisner (2006) on the Hausa newswire dataset, there might not be enough training data to rely on the n-best list. |
The advantage of the last version is that it can be understood by an area chair (who has expertise in the subarea) without looking for line numbers.
3. Check for common review issues I2 I10
Judging whether a research paper is “good” is an objectively hard task, and over the past conferences, we collected a list of common problems, which is presented below. Such comments may point at legitimate problems with the paper, but they are not always “weaknesses”. This can happen even to experienced reviewers, and it’s worth checking your review for these problems before submitting.
| Heuristic | Why this is problematic |
| H1. The results are not surprising | Many findings seem obvious in retrospect, but this does not mean that the community is already aware of them and can use them as building blocks for future work. Some findings may seem intuitive but haven’t previously been tested empirically. |
| H2. The results contradict what I would expect | You may be a victim of confirmation bias, and be unwilling to accept data contradicting your prior beliefs. |
| H3. The results are not novel | If the paper claims e.g. a novel method, and you think you've seen this before - you need to provide a reference (note the policy on what counts as concurrent work). If you don't think that the paper is novel due to its contribution type (e.g. reproduction, reimplementation, analysis) — please note that they are in scope of the CFP and deserve a fair hearing. |
| H4. This has no precedent in the existing literature | Believe it or not: papers that are more novel tend to be harder to publish. Reviewers may be unnecessarily conservative. |
| H5. The results do not surpass the latest SOTA | SOTA results are neither necessary nor sufficient for a scientific contribution. An engineering paper could also offer improvements on other dimensions (efficiency, generalizability, interpretability, fairness, etc.) If the authors do not claim that their contribution achieves SOTA status, the lack thereof is not an issue. |
| H6. The results are negative | The bias towards publishing only positive results is a known problem in many fields, and contributes to hype and overclaiming. If something systematically does not work where it could be expected to, the community does need to know about it. |
| H7. This method is too simple | The goal is to solve the problem, not to solve it in a complex way. Simpler solutions are in fact preferable, as they are less brittle and easier to deploy in real-world settings. |
| H8. The paper doesn't use [my preferred methodology], e.g., deep learning | NLP is an interdisciplinary field, relying on many kinds of contributions: models, resource, survey, data/linguistic/social analysis, position, and theory. |
| H9. The topic is too niche | A main track paper may well make a big contribution to a narrow subfield. |
| H10. The approach is tested only on [not English], so unclear if it will generalize to other languages | The same is true of NLP research that tests only on English. Monolingual work on any language is important both practically (methods and resources for that language) and theoretically (potentially contributing to a deeper understanding of language in general). |
| H11. The paper has language errors | As long as the writing is clear enough, better scientific content should be more valuable than better journalistic skills. |
| H12. The paper is missing the [reference X] | Per ACL policy, missing references to prior highly relevant work is a problem if such work was published (which is not the same as 'put on arXiv') 3+ months before the submission deadline. Otherwise, missing references belong in the "suggestions" section, especially if they were only preprinted and not published. Note that for resubmissions, papers are only required to make comparisons to highly related relevant work published at least three months prior to the original submission deadline. |
| H13. The authors could also do [extra experiment X] | I10 It is always possible to come up with extra experiments and follow-up work. But a paper only needs to present sufficient evidence for the claim that the authors are making. Any other extra experiments are in the “nice-to-have” category and belong in the “suggestions” section rather than “reasons to reject.” This heuristic is particularly damaging for short papers. If you strongly believe that some specific extra comparison is required for the validity of the claim, you need to justify this in your review. |
| H14. 🆕 The authors should compare to a 'closed' model X | I10 Requesting comparisons to closed-source models is only reasonable if it directly bears on the claim the authors are making. One can always say "it would be interesting to see how ChatGPT does this", but due to methodological problems such as test contamination and a general lack of information about 'closed' models, such comparisons may not be meaningful. Behind this kind of remark is often an implicit assumption that scientific questions can only be asked of the “best” models, but pursuing many important questions requires a greater degree of openness than is offered by many of today’s “best” models. |
| H15. The authors should have done [X] instead | A.k.a. “I would have written this paper differently.” There are often several valid approaches to a given problem. This criticism applies only if the authors’ choices prevent them from answering their research question, their framing is misleading, or the question is not worth asking. If not, then [X] is a comment or a suggestion, but not a “weakness.” |
| H16. Limitations != weaknesses | No paper is perfect, and most *CL venues now require a Limitations section. A good review should not just take the limitations and list them as weaknesses or reasons to reject. If the reviewer wishes to argue that acknowledged limitations completely invalidate the work, this should be appropriately motivated. |
| H17. Citation count != validity | Most papers, especially those published outside of the famous research groups, receive relatively few citations. This does not entail that the results in little-cited papers are not valid. If everyone builds only on a few famous papers, only a narrow range of research directions will be developed. |
If you have something like the above listed as a “weakness” of the paper, do try to revisit the paper with an open mind. Both the authors and the ACs will be aware of these guidelines and can refer to them in discussion/meta-review.
REVAS tool
ARR is currently experimenting with a review assistant tool, which you may optionally use to check for some common review issues: https://revas.mbzuai.ac.ae/. At present, it can help you to automatically identify if the review may exhibit some of the above review issues.
🆕 4. Check for common problems in NLP papers
As a counter to common problems with reviews, there are also common problems with NLP papers. We do ask you to watch out for these and point them out when you see them. Above all else, published research should at least be technically sound and appropriately scoped. As with the above reviewer issues, it’s a case-by-case evaluation: some things in the list below may be appropriate in a given context, given that they are sufficiently motivated. We provide codes for different types of issues (e.g. M1, G2…) that can be referenced in discussions.
| Issues with methodology (M) | |
| M1. LLM-only evaluation without validation | If LLMs are used as automated evaluators, is their reliability in this context sufficiently validated? |
| M2. Reproducibility issues | Are there enough details to reproduce the experiments, including hyperparameter selection? Is it clear whether the code/data/etc will be publicly available? If not, is that sufficiently motivated? If so, are they at least provided for reviewer evaluation? If you can't find this in the paper, check the authors' answers for the Responsible NLP checklist. You are not obligated to run the code, especially if it's computationally expensive, but you are welcome to do this to substantiate your assessment of the paper. Note: reproducibility score refers to reproducibility (being able to run the same experiment with roughly the same results) rather than replicability (getting similar results after reimplementation or on different models/data). Since reviewers are not obligated to run anything, the scope of ARR reproducibility score is to at least assess whether enough details/code is provided for reproducibility. |
| M3. Undisclosed data quality issues | The papers that provide resources may be accompanied by full datasets or samples. You are not obligated to check this data. But you are welcome to, and if you notice issues that are not disclosed/discussed in the paper — this is a serious problem to bring up. |
| M4. Unmotivated selection | Any paper will have a limited number of models and benchmarks. But it should be clear why this sample was selected, and that motivation should be directly linked to the scope of the claimed contributions. You may feel that you would have selected a different sample, but that's ok, as long as the sample that the authors selected is appropriate for their claims. |
| M5. Incomplete sets of assumptions or proofs | All assumptions should be clearly stated. If the paper contributes formal statements (theorems, propositions, lemmas, corollaries), they should be supported by complete and correct proofs. Proofs can be delegated to appendices, as long as they are properly referenced in the main text of the paper. |
| Issues with terms of artifact sourcing or release (T) | |
| T1. Ethics issues with data collection | If the paper involves annotation or data collection from humans, the responsible NLP checklist has relevant questions about ethics approval, compensation etc. Issues related to that are considered not by the main conference reviewers, but by ethics reviewers. If you feel that these are satisfactorily addressed, you can flag the paper for ethics review. |
| T2. Unclear license / release terms | If the paper contributes some artifact (e.g. a dataset or a trained model), is it spelled out under what terms it would be released? Note that such decisions may vary by jurisdiction. Your role is not to make legal judgments (especially from the point of view of your own institution), but to make sure that the authors are clear about what they are doing. |
| Issues with experimental results (R) | |
| R1. Analysis issues | Inappropriate/misleading statistics or data presentation, p-hacking, presenting the 'best' results out of an unknown number of trials (including prompt tuning or engineering), baselines that are not sufficiently well-tuned for a fair comparison (including prompt tuning or engineering). |
| R2. Inappropriate scope of the claims | The authors evaluate a sample that does not represent the population about which the claim is made. E.g., a few QA benchmarks !="reasoning" or "understanding", LLMs of a certain size != LLMs. |
| R3. Hypotheses/speculations presented as conclusions | Every claim that is made has to be based on evidence or arguments (the authors' or from other work), or clearly marked as conjecture/speculation. |
| R4. Misleading or inappropriate framing, overclaiming | E.g., concluding from benchmark evaluation that LLMs generally 'understand' language, without validating that construct. |
| R5. Inappropriate or missing statistical significance assessment | Ideally, at least the main experimental results should be accompanied by appropriate information about their statistical significance (error bars, confidence intervals, statistical significance tests), details about how this was computed, and discussion of factors of variability and any assumptions. Effect size estimation is also very welcome. |
| General issues (G) | |
| G1. Unclear research question or contribution | Is it sufficiently clear what knowledge gap the authors are addressing and what they contribute to it? The paper's contributions should be clearly stated in the abstract and introduction, along with any important assumptions and limitations. Aspirational goals can be included as motivation, as long as it is clear that these goals are not attained by the paper. |
| G2. Reliance on a bad precedent | Sometimes methodology choices or arguments are motivated by appeal to precedent in previously published papers, and sometimes you may feel that that precedent is by itself not sound, or was disproved, or does not reflect the current best practice recommendations. In such cases, you are welcome to explain your position and discuss it with the author and other reviewers. Afterwards please update your review and explain clearly (for the authors and AC) why you changed your position or not. |
| G3. Missing/misrepresented related work | The authors are not expected to be aware of all the preprints within the past 3 months, but they are expected to be aware of work prior to that (at least the work that was reviewed and officially published). It is important that they fairly represent the contributions from the other work, and the respective novelty of their work. Note that (non-)reproduction studies are proper contributions in scope of ARR CFP, as long as they are appropriately presented. |
| G4. Key terms too vague and not defined | It is unclear what the authors mean by X, and they do not specify or reference their definition. |
| G5. Misleading/incorrect citations | The cited papers do not clearly say — or even contradict — what is attributed to them. This is a particularly worrying trend as more and more authors turn to LLM-generated summaries instead of reading the papers in question. |
5. Check that your scores reflect the review I3
ARR reviewers are asked to provide three scores: soundness, excitement, and overall recommendation.
I3 The soundness scores must be justified by the text of the review . If you give a low Soundness score without finding any major faults, this means that your review is not a faithful explanation of your recommendation, and you need to revise it. One possible reason for low soundness scores without sufficient justification could be reliance on some unconscious bias or heuristic, like the ones listed in the previous section. Likewise, low reproducibility scores should be justified.
Sometimes you may find the work sound, but not something that is interesting for you personally. Such preferences are more subjective and should be reflected in a separate excitement score, which is orthogonal to the assessment of the soundness of the paper. Excitement scores reflect our personal taste, and so do not necessarily come with explicit reasons.
The Overall assessment score is an explicit recommendation for the outcome of this paper, if it were committed to an *ACL venue. This is a composite score reflecting your assessment of soundness, excitement, and also other factors like novelty and impact. All papers recommended for Findings and main conferences are expected to be sufficiently sound and reproducible, but you may consider a paper worthy of the main conference even if you personally are not excited about it. For example, improvements in efficiency of some algorithm, or creating a high-quality resource for a language/domain that does not yet have resources of that type may not sound very novel or exciting, but you may still consider it a significant contribution due to its potential impact (for its target community).
6. Check that the tone is professional and neutral I4
Above all, a good review should be professional and neutral, if not kind. A key goal of peer review is to help the authors improve their papers. As an anonymous reviewer, you are in a position of power, and the written medium makes it easier to be more dismissive and sarcastic than if you were communicating with the authors face-to-face. Unfortunately such reviews are not uncommon.
Consider that you may well be addressing someone who is only starting on the research path. And/or someone struggling with stress and other mental health issues. And/or someone who has been less lucky with their school and advisors. Academic lives are already stressful enough, and we do not need to inflict extra damage on the mental health of our colleagues with sarcastic or insulting reviews. Write the review you would like to get yourself.
The fact is, authors and reviewers are actually the same people: the conference crowd lining up for coffee, happily chatting with each other about the grand problems even if they do not always agree. Why can’t we do peer review in the same spirit of fun intellectual interaction with colleagues?
Just like the conference coffee break chats, reviewing is in fact, mutually beneficial: in exchange for feedback, the reviewers get to have the first look at cutting-edge research. Just like the coffee breaks, where you do not necessarily meet only the people working in your subsubfield, peer review may expose you to new techniques. Since there is careful written communication in the authors’ response, you may even find that you were wrong about something, which is a much faster way to learn than making the same mistake in your own research.
Not to mention, someone out there is reviewing your papers too. The more rude or dismissive reviews there are, the more of a norm they become, and the higher the chances you will get one yourself in the future.
What should I do if I find a serious problem late in review process?
You should still file the reviewer checklist indicating the type of the problem that could warrant desk rejection. If this comes in time for chairs to confirm the problem and issue the desk reject before author response period, you will no longer have to review that submission. If any other reviews were already completed before desk rejection, the authors will have to resubmit, but they will still benefit from the feedback. It is also possible to edit the checklist you submitted before, if you find you missed something that should have been reported there.
If the case is tricky, you may also initiate a discussion of the case among reviewers. If the desk reject case is not very clear, but there are serious content issues, it is also possible to simply give the paper a low score. The same applies in cases where you discover a serious methodological problem (e.g. p-hacking, superficial literature review).
✅ TASK 4. Update your assessment after the authors’ response and discussion I11
Author response and updating the assessment
Due to abuse on the side of the authors, ARR author response is currently limited to one response to each individual reviewer + one general response. In turn, reviewers are expected to at least acknowledge the authors’ response; in particular, we ask that you update your review taking into account any important clarifications the authors made and any violations of the reviewer guidelines the authors identified. You are probably well aware that, as an author, it is rather depressing to spend a lot of time carefully preparing responses to the reviews, only to see in the notification that the reviews did not change at all.
- If you do not find the response convincing, please explain why. Then the authors will at least know that their response was not convincing (rather than just not read), and that is still useful information for improving their work.
E.g., Update: the authors responded, but none of the issues were addressed sufficiently to change my assessment [adding briefly what you found unconvincing] - If you find that at least some of your concerns were sufficiently addressed, please update the scores/text of your review, according to the gravity of the resolved issues. To make it clear what the changes are, please do not just edit the old review but add in the end a short statement.
E.g., Update: the issues with X and Y were resolved in the discussion, and I updated my scores. - If you would like to discuss something with the authors, you are encouraged to discuss it for as long as there’s time, but please keep in mind that the AC is unlikely to read very long discussions (we ask them to read at least top 2 author responses per reviewer thread). We recommend asking for clarifications on the most important points first so that this information is more likely to be noticed by the AC.
After the author discussion period ends, there is a short period of time for reviewers to finalize their reviews based on any responses from the authors and/or other reviews. The full timeline is communicated in the cycle emails. After the reviews are finalized, the authors can submit review issue reports.
Discussion with other reviewers
In ARR reviewer discussion may happen throughout the process, i.e., both before reviews are sent to authors and after the authors respond. Any reviewer or the AC can initiate a discussion. You can discuss the authors’ response, possible desk reject cases, etc.
Possible influence of other reviewers. When you see the reviews by the other reviewers, be aware that they may affect your own judgment in several ways because of social psychology effects. If you pointed out a weakness and then saw it also pointed out by someone else, you may feel it is a more severe problem than you originally thought. You may “discard” your own opinion if you see the opinion of someone you believe to be more senior/experienced/famous. If your original opinion was very positive, in the face of a strongly negative review, you may be tempted to “converge to the mean” (or the other way round). Ask yourself if this is really warranted, and whether this may be reflecting some core dispute between approaches/methodologies etc. Strong disagreements may be an indication that the paper is doing something unusual and interesting.
How to review resubmissions
Papers that are resubmissions have a link in the “Previous URL” field in the metadata, and it should point to the previous submission.
Beware of papers desk-rejected for anonymity issues!
In some cases the previous submission was desk rejected. If so, there will be a comment from the editors at the top of the forum, stating the reason for the desk rejection. Please note what it was. If it was due to anonymity violations, please avoid looking at the pdf of the previous submission to not accidentally discover the identity of the authors.
If the authors decide to resubmit their paper to another cycle of ARR, they will have the choice to request the same or different reviewers. However, sometimes the same reviewers are not available when requested. This leads to the following three types of reviewers for resubmissions (to be discussed in turn below):
- Repeat: If the authors requested the same reviewers, and these reviewers are available in the cycle, then they are repeat reviewers.
- Substitute: If the authors requested the same reviewers, but one or more of these reviewers is not available in the cycle, then new reviewers will be substituted for the unavailable ones.
- Fresh: If the authors requested different reviewers, then new reviewers will be assigned who will have a fresh perspective on the paper.
Note that in all three cases, consistent with ACL policy, resubmitted papers are only required to make comparisons to highly related relevant work published at least three months prior to the original submission deadline, though they are encouraged to discuss contemporaneous work where feasible.
Repeat reviewers
If you are a repeat reviewer, you will see the authors’ revision notes, typically listing and discussing the changes they made in the new version of the paper. Starting from December 2024, ARR will require that authors include such a summary of revisions for resubmissions. You will need to reread the paper and comment on to what extent the authors successfully responded to the previous reviews. Please indicate that you read their revision notes and say whether you feel weaknesses were adequately addressed or not.
In your review, you should refrain from raising new issues that were not discussed in the first round of reviews — otherwise, if resubmissions get a new round of weaknesses identified, then authors will never be able to move forward with commitment. The exception is when the revisions resulted in contradictory findings or questionable results not present in the first round of reviews.
Note that it is because of this stage that it is of utmost importance that in the first review, you are very clear about what kinds of improvements you want and how much of a difference they would make. If the authors are asked to perform a lot of extra experiments, but you fundamentally dislike the paper to the extent that nothing they could do would considerably change your opinion, this is not a good use of everybody’s time and resources.
Substitute reviewers
As with the repeat reviewers case above, if you are substituting for one of the original reviewers, the aim here should be to avoid an endless cycle of paper resubmissions. You should therefore proceed as follows:
- After reading the paper to form an initial impression, you should look over the author revision notes and the previous reviews (click on the “Previous URL” link in the submission metadata).
- After reading the revision notes, you should consider whether any weaknesses you may have identified in your initial read of the paper represent (i) previously identified weaknesses that were not adequately addressed; (ii) newly raised issues that represent critical issues of soundness; or (iii) other newly raised issues.
- With these categories in mind, you should proceed to write your review, where (i) you explain the reasons why the revisions did not adequately address previously identified weaknesses; (ii) you explain the reasons why newly raised issues represent critical issues of soundness; and (iii) you reframe any other newly raised issues as suggestions for improvement.
Fresh reviewers
As a fresh reviewer, you should form your own opinion of the paper. Note that you will not initially see the previous reviews or the authors’ revision notes (new in August 2023), but after you submit your review, you will gain access to the old reviews and the revision notes (click on the “Previous URL” link in the submission metadata). At this point, you should check the revision notes to see whether any weaknesses in your review were previously identified, and if so, edit your review to explain why the revisions were not fully adequate to address the weaknesses in question. You may also consider whether the previous reviews identified weaknesses that you hadn’t thought of, and if so, whether you agree that they represent serious concerns meriting inclusion in your review.
FAQ
Q: How can I ask a question not answered in this FAQ?
-
For questions on how to use OpenReview to complete your tasks, please contact our Support Team (support@aclrollingreview.org);
-
For technical difficulties, errors, and generally in case of suspicious behavior of the OpenReview system, please contact the Tech team (tech@aclrollingreview.org);
-
For content-based questions (e.g., about the submissions themselves, doubts about reviewer tasks, etc.), please contact editors-in-chief at editors@aclrollingreview.org
Q: I’m new to reviewing, any tips?
Overall, these guidelines cover each step of the process, including a list of common problems in both reviews and NLP papers to watch out for. There is also the REVAS review assistant you can use to improve your review.
If you are new to reviewing, it may be a good idea to prepare the review earlier and ask more experienced people in your network for feedback. Some ACs may also offer feedback for reviews that come in good time. As a secondary reviewer, you are expected to be mentored by the primary reviewer.
How much time will you need for reviewing? That varies by reviewer, paper, and experience. A way of estimating it would be to calculate what your average time for (a) skimming + in-depth reading of a paper is that is as close to your area as the submission, (b) writing and editing about half a page of an article. Ideally, this would be spread over a few days, because the first-impression draft may be tainted by a knee-jerk reaction to the paper’s methodology or results. Then, during the discussion period, you need to set aside some time to check the authors’ response, discuss and/or update the review as needed. It would be a good idea to actually clock yourself doing the reviewing work from time to time, so that you know how long it takes (and how much variance there is), and plan accordingly next time.
Q: How to get assigned to papers that match your interests well?
When you accept the invitation to review for ARR, please make sure that your Semantic Scholar profile is accurate and up-to-date. This information is used in the automatic paper-reviewer matching, so the more accurate it is, the more likely you are to get papers in your area.
Your profile should also include a link to your DBLP page and author page in ACL Anthology. This information is used to estimate your seniority and experience with *CL conferences, used for automatic checks of reviewers who fulfill the reviewing workload requirement for the authors. We are aware that for some authors with common names there are currently some disambiguation issues; in the future ACL Anthology plans to implement ORCID integration.
Hence, after you have provided your Semantic Scholar ID and pulled in papers from DBLP, go through the papers listed in your profile. Delete those that do not match your current expertise (e.g. papers from long ago in areas in which you no longer work, papers that were for a side project). Also delete any that you did not (co)author.
Q: How do I do X in OpenReview?
We have a tutorial for performing common actions on OpenReview: viewing your current tasks, adding reviews, participating in discussion, contacting ACs. We also have a post describing the ARR review form in detail.
At any stage, you can view your pending tasks by logging in to OpenReview and opening the following link:
https://openreview.net/group?id=aclweb.org/ACL/ARR/<YEAR>/<MONTH>/Reviewers#reviewer-tasks
E.g. for NAACL 2024 cycle it is:
https://openreview.net/group?id=aclweb.org/ACL/ARR/2024/October/Reviewers#reviewer-tasks
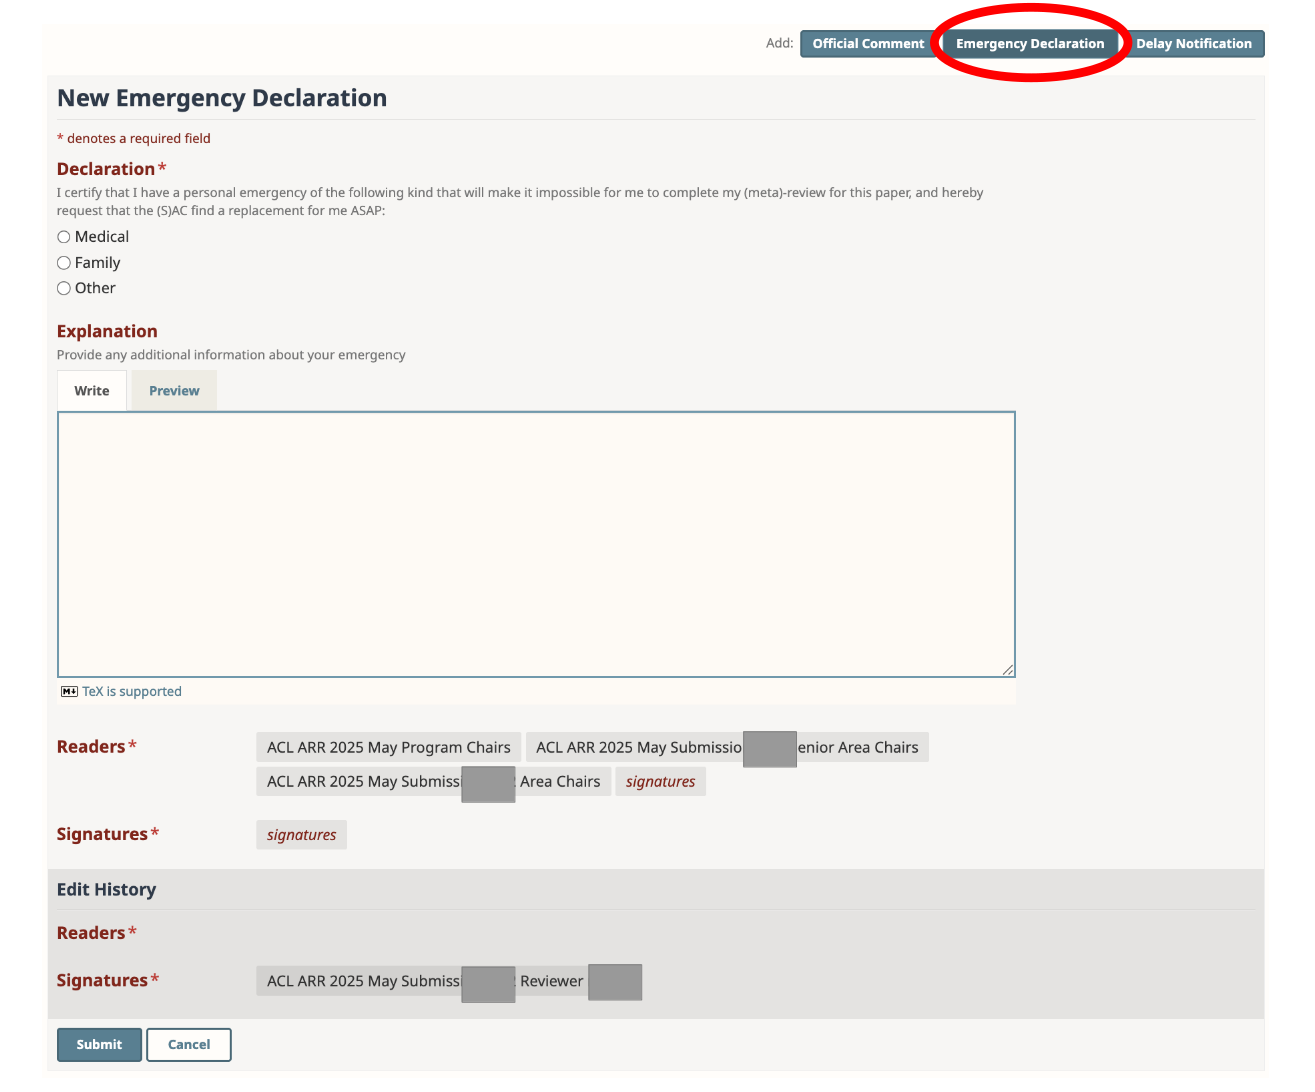
Q: What should I do if I cannot complete my assignment on time due to a personal emergency?
If your ability to complete your assignments on time has been compromised due to a personal emergency, please reach out to your ACs and SACs as soon as possible by filling out the Emergency Declaration form on the page for each paper you are assigned to. It is important that you use this mechanism, rather than personal emails to the chairs or editors. This form places the record of your situation in the forum, so that all chairs can see it and avoid unnecessary emails to each other. It is also used for our analysis of which reviewers received assignments and simply went missing without due warning.
Once this form is filled, the ACs and SACs will then try to find an emergency backup reviewer for each paper. Note that this creates extra work for everyone involved and may be detrimental to review quality, so you should only use this option in real cases of emergency.
Q: How can I notify chairs when I will submit my review?
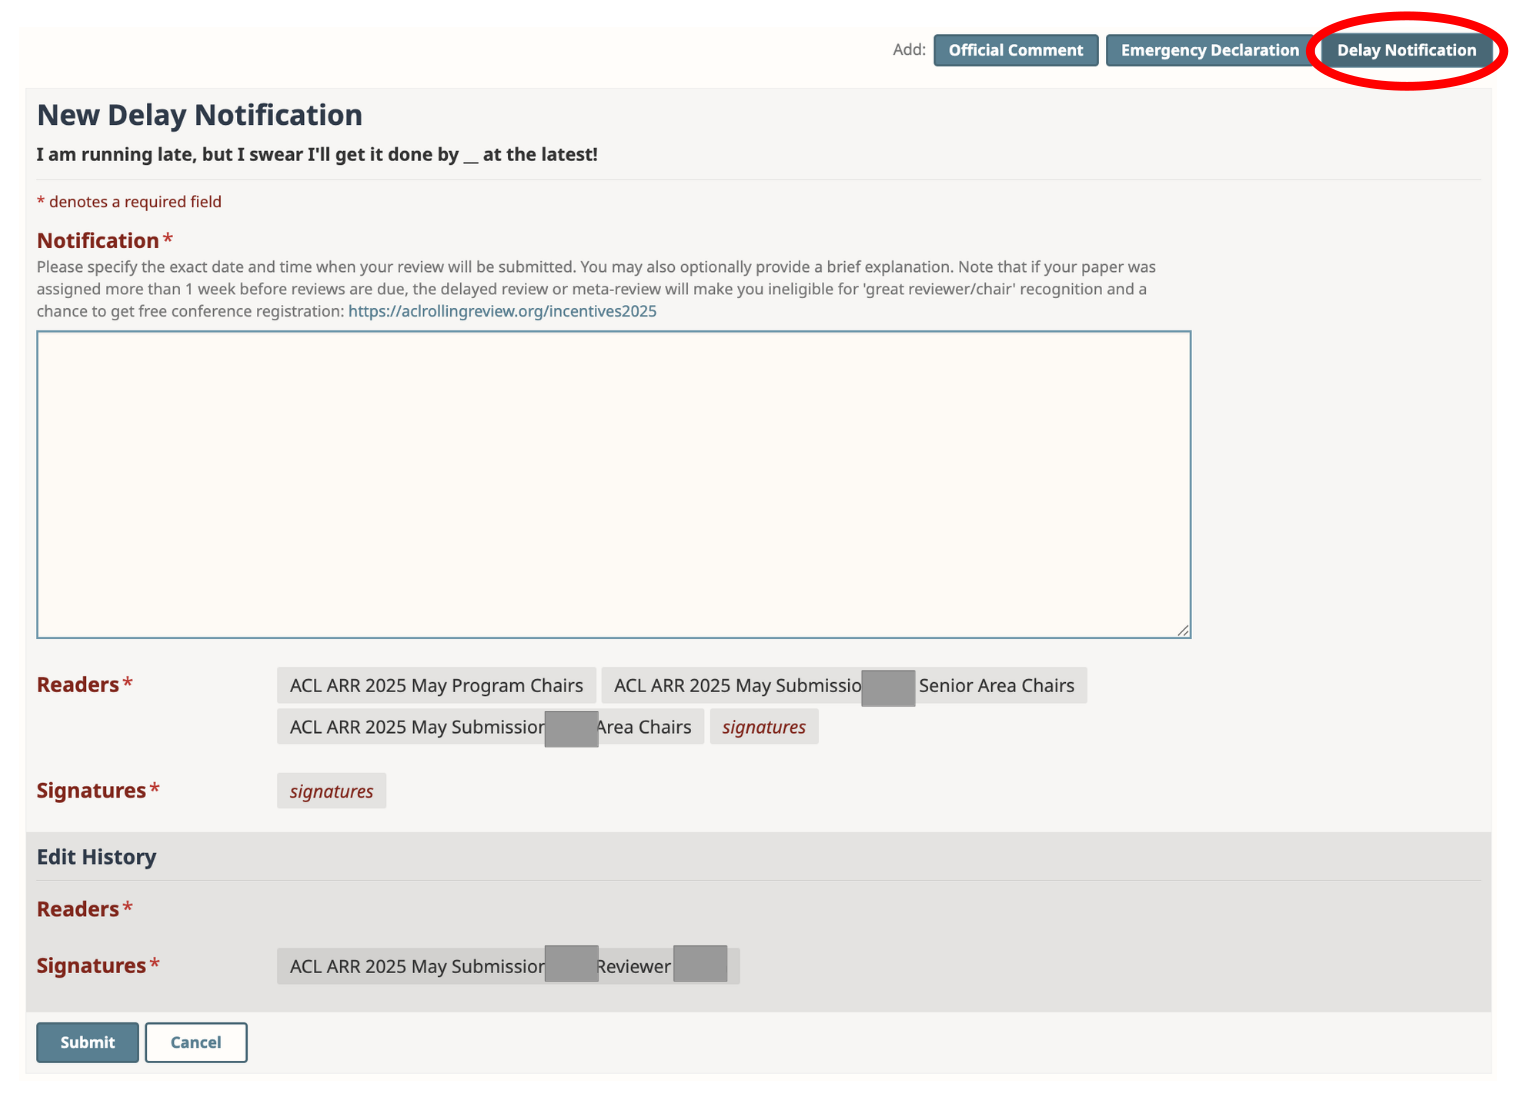
If due to unforeseen circumstances you cannot complete some of your assignments on time, but you will complete them with a small delay, please reach out to your ACs and SACs as soon as possible by filling out the Delay Notification form on the page for each paper where the review will be delayed. The form asks to specify the exact time (with timezone) when your review will be in, and to provide an explanation. It is important that you use this mechanism, rather than personal emails to the chairs or editors. This form places the record of your situation in the forum, so that all chairs can see it and avoid unnecessary emails to each other. It is also used for our analysis of which reviewers received assignments and simply went missing without due warning.
Once this form is filled, the chairs will be able to tell easily that they do not need to not look for an emergency reviewer. This would save everyone time and energy on extra communication, and over-assigning reviews. This mechanism should only be used as an exception, and not the general practice. Delayed reviews or meta-reviews disqualify you from the ‘great reviewer’ recognition and a chance for free registration (unless the review was assigned late in the first place, i.e. less than 1 week before the reviews due date).
Note that reviewers/ACs who are also authors — and their co-authors — will not see the reviews of their own submissions until they have completed their assigned reviews/meta-reviews. Where reviews/meta-reviews are late and no emergency declaration has been posted, access is withheld until the reviews/meta-reviews are in, or until two days before the end of the author response period in the worst case.
Q: Should I flag this for ethics review?
The general program committee members are not expected to be ethics experts. If you see something that you think could be problematic, you can flag the paper to be reviewed by a dedicated ethics review team. Generally, reviewers should look for issues with use of data sets and how they were collected, potential abuse, and disadvantages for minority groups. Please consider the ethics flagging guidelines as needed. Many commonly asked questions relevant to the ethics review are a part of the Responsible NLP checklist, and so the authors have already answered them for you as part of their submission.
How do you tell if the authors’ answers are satisfactory? There is no single number for what counts as “fair pay”, nor a simple rule that would account for “legal grounds for data collection/processing”. The laws and practices at the authors’ home country and institution probably differ from yours, and it would be unfair to expect that the authors would follow exactly your own practice. So fundamentally, the authors make their case for what they did, and try to convince you that this was appropriate — similarly to all other aspects of paper review. That being said, the broad principles of the ACM Code of Ethics need to be upheld, even for the authors from the countries that did not ratify the human rights convention. If you believe there may be a serious ethical issue, but you lack the expertise to evaluate it, you may flag the paper for a separate review process by the ACL ethics committee. They will make a recommendation as to whether the paper should be accepted, revised, or rejected on ethical grounds.
Q: Can I use generative AI?
The following recommendations come from the ACL policy on publication ethics.
- The reviewer has to read the paper fully and write the content and argument of the review by themselves, subject to the secondary reviewer policy described above, and it is not permitted to use generative assistance to create the first draft. This requirement extends to the meta-review, and the reviewer has to write any meaningful argumentation in the meta-review by themselves.
- Generative assistance should be used responsibly. For instance, it is reasonable to use writing assistance to paraphrase the review, e.g. to help reviewers who are not native speakers of English. It is also reasonable to use tools that help to check proofs.
- Neither reviewers nor editors should upload a submitted manuscript or any part of it into a non-privacy preserving generative tool as this may violate the authors’ confidentiality and intellectual property rights and, where the paper contains personally identifiable information, may breach data privacy rights.
- This confidentiality requirement extends to the peer review report, as it may contain confidential information about the manuscript and/or the authors. For this reason, neither reviewers nor editors may upload their peer review report into a non-privacy-preserving generative tool, even if it is just for the purpose of improving language and readability.
The ACL publication ethics committee is currently developing a full process for investigating and taking action on scientific malpractice, similar to the process for investigating professional misconduct. There is already a policy on review incentives and sanctions, including temporary bans on (re-)submission or commitment to ACL venues.
To add to the above points, the reviews that look like they were written by ChatGPT overall decrease the faith in the peer review process. According to this study, there is more generated text in ‘reviews which report lower confidence, were submitted close to the deadline, and from reviewers who are less likely to respond to author rebuttals’. All these factors generally correspond to the type of unmotivated reviewer that, as authors, we would prefer to avoid. The increased ratio of such reviews also attunes the community to reviews that sound like they were generated. Generally, reviews are valued for their content rather than language, so your thoughts are more likely to be appreciated if they come in your voice (even if with linguistic imperfections).
Finally: some authors actually count on you to use generative AI, and include hidden prompt injections intended to manipulate your assistant into giving a positive review! If you notice anything like that, please raise it with the chairs, such submissions should be desk rejected.
What about the authors, can they use generative AI? The ACL policy on publication ethics discusses various cases with different degrees of acceptability. Note that the authors are obligated to disclose their use of generative AI, and there is a question about that in the end of the Responsible NLP checklist (search for ‘E1’).
Q: How do I contact the area chair?
You can contact your AC either directly or through OpenReview (see the OpenReview tutorial):
- To communicate through OpenReview, you should see a button labeled “Official Comment” at the top of the paper forum. Click on it to open a message form. For messaging exclusively the ACs, please select only “area chairs” in the “Readers” field of the form.
- To communicate through email, you can find the name of the AC on the “Paper Assignments” page in OpenReview, and click on their name. Their email will be anonymized on the OpenReview page itself (for privacy reasons), but you can often find it by clicking on the “Homepage” link or otherwise searching for their contact information by following the links in the profile.
Q: Can I use a secondary reviewer?
Starting with the April 2024 cycle, we have rolled out a secondary reviewing feature. We understand that especially for more senior reviewers, having the ability to collaborate in reviewing the papers is convenient and helps train new reviewers.
The main reviewer is still responsible for submitting the work, including the review itself, in a timely manner. They are still the point of contact for ARR, and will receive all of ARR communication. They are responsible for the quality and the sustained engagement of the secondary reviewer after author rebuttal.
The secondary reviewers were initially declared via a ‘secondary reviewer’ field in the review form, which was only used to acknowledge the reviewers. Starting in May 2026, it is possible to declare the reviewers via a new ‘Declare a secondary reviewer’ button, which brings up the following interface:

The secondary reviewers, like the primary reviewers, are not be visible to the authors. They are added to the list of reviewers for that cycle after completion of the assignments. Conferences publish lists of their reviewers in the proceedings, and secondary reviewers can request reviewer certificates.
New in May 2026: secondary reviewers should now be able to view the forums and see the author response. Any responses to author response, or updates to the original review, still need to be submitted by the primary reviewer (since they take responsibility for the review). This change is intended to help in cases where the senior researchers mentor the junior researchers serving as secondary reviewers. The secondary reviewers can now follow the discussion themselves, without needing to wait for the primary reviewers to share anything, and they can let the primary reviewers know if it is necessary to update the review and/or post a further reply.
Q: Why is peer review so inconsistent?
You may have heard of the NeurIPS experiments (2014, 2021), in which the same papers were assigned to two sets of reviewers. Their results suggested that peer review is fairly reliable in rejecting the low-quality submissions, but for the rest, the final decisions of the two committees are at random chance level. This is obviously a frustrating situation for the authors, going through rounds of seemingly arbitrary rejections. Besides the noise in this process, there are many factors that could contribute to this situation, including the following:
- Variance in reviewer experience and training. Some inexperienced reviewers do not receive appropriate training.
- Variance in understanding the evaluation rubrics. Reviewers may differ in what counts as a “weakness” - a fundamental flaw or a lack of clarification experiment? Similarly, how exactly should the “overall recommendation” balance a reviewer’s own interest in the topic with the thoroughness of the research?
- Implicit biases that we all have due to our social and academic backgrounds. The same approach may receive different evaluation if it is tested on a popular or a niche task, on English or any other language, with focus on engineering or linguistic aspects, and if it had been preprinted by a well-known lab and has received much attention. In case of submissions that get deanonymized due to preprints and social media, we may also be biased in favor of well-known authors and/or widely-discussed papers.
These guidelines are a part of an effort to improve the overall quality of reviews at *CL conferences, aiming to address the above issues. We discuss the overall structure and philosophy of the process for first-time reviewers, clarify the ARR principles and the review form, and address some of the cognitive and social biases that undermine peer review.
Note that reviewer guidelines address only the variance in the review process, not the acceptance decisions. Top-tier conferences usually have more high-quality submissions that receive good reviews than they can accept, and then the decisions are also motivated by space and quota constraints, and editorial priorities of the chairs. 🆕 See sec. 7 of ACL’23 report for analysis of the effect of reviews, meta-reviews, and SAC recommendations on the final decision.
Q: I think I should have heard from ARR, but I haven’t seen any emails. What’s going on?
It’s possible that the emails have been marked as spam – check your spam folder! ARR does not use email tracking: we know if email bounces, but we don’t know if you have seen a message.
Q: What is the review report license agreement about?
At ARR you can donate your peer review reports to an open public dataset of peer reviews and paper drafts (see our blogpost on the data collection for details). You can contribute your data to the corpus via signing the review report license transfer agreement, which you can find in your task log on OpenReview. You have to make this decision for each cycle and you donate all review reports of a cycle in bulk.
Q: How are paper assignments determined? In particular, how are areas used?
We generate an assignment automatically based on areas, prior work, and languages involved. We also try to ensure at least one reviewer is a non-student, and that no two reviewers are from the same institution. This assignment is checked by the AC, who changes reviewers as needed. Regarding areas, reviewers choose multiple areas that they have expertise in while authors choose a single area at submission time. We strongly encourage the matching algorithm to assign reviewers that match the area.
Q: I no longer wish to be a reviewer for ARR. How can I withdraw myself from the pool?
Please contact the EICs to have yourself removed.
Q: How to Request a Max Load (and Declare Unavailability) in OpenReview
See these guidelines.
Changelog
- 22.10.2025 Updates related to the sustainable reviewing policy.
- 01.05.2025 Updates related to the new ACL policies on incentives in peer review.
- 21.10.2024 A major update based on ACL’23 edits (Anna Rogers, Jordan Boyd-Graber), internal ARR documentation, and NeurIPS paper checklist. Includes new guidlines related to ACL publication ethics and anonymity rules, guidance for requesting experiments involving closed-source LLMs, new section on common problems in NLP papers, and codes for common review issues that can be flagged by reviewers. Feedback from Michael White, Noah Smith, Mausam, Marzena Karpinska.
- 15.05.2024 Anonymity policy updates
- 27.09.2023 New reviewing page, AI question in the checklist. Comments and corrections by Aurélie Névéol, Amanda Stent, Sebastian Riedel, Preslav Nakov.
- 10.08.2023 Instructions on access to old reviews
- 02.11.2021 First version of this document (Anna Rogers, Isabelle Augenstein)
Extra resources
General peer review process
- EACL 2021 tutorial on peer review, pt. II - The Actual Review (Karën Fort): slideslive, slides
- ACL’23 program chair report has extensive statistics and analysis for different aspects of the peer review process at that conference, including the impact of reviewer and AC scores and various aspects of paper-reviewer matching on the final outcome
General advice and reviewing philosophy
- Advice on peer review from Mirella Lapata, Marco Baroni, Yoav Artzi, Emily M.Bender, Joel Tetreault, Ani Nenkova, Tim Baldwin: https://acl2017.wordpress.com/2017/02/23/last-minute-reviewing-advice/
- A podcast interview with Noah Smith: https://soundcloud.com/nlp-highlights/77-on-writing-quality-peer-reviews-with-noah-a-smith
- Rebekah Baglini and Christine Parsons on how to avoid harsh language in peer review: https://www.nature.com/articles/d41586-020-03394-y
Examples of good reviews
- Two examples of peer review from NAACL 2018: https://naacl2018.wordpress.com/2018/01/20/a-review-form-faq/
Reviewing specific aspects of papers
- Jesse Dodge and Noah Smith on the reproducibility checklist: https://2020.emnlp.org/blog/2020-05-20-reproducibility/
- EACL 2021 tutorial on peer review, pt. III - Reviewing Results Section (Kevin Cohen): slideslive, slides
- EACL 2021 tutorial on peer review, pt. IV - Reviewing Conclusion Section (Kevin Cohen): slideslive, slides
Reviewing different types of papers
- COLING 2018 review form for different paper types has great questions to ask yourself when reviewing engineering, resource, reproduction, survey and computational linguistics papers: http://coling2018.org/paper-types/
- Anna Rogers. Peer review in NLP: reject-if-not-SOTA https://hackingsemantics.xyz/2020/reviewing-models/
- Anna Rogers. Peer review in NLP: resource papers https://hackingsemantics.xyz/2020/reviewing-data/
Cognitive and social biases in peer review
- Anna Rogers, Isabelle Augenstein. What can we do to improve peer review in NLP? https://aclanthology.org/2020.findings-emnlp.112/
- EACL 2021 tutorial on peer review, pt. V: Reviewer Biases (Anna Rogers): slideslive, slides
- EACL 2021 tutorial on peer review, pt. VI: Anonymity in Peer Review (Anna Rogers): slideslive, slides
Ethics
- NAACL 2021 Ethics FAQ: https://2021.naacl.org/ethics/faq/
- EACL 2021 tutorial on peer review, pt. VII - Ethics and Reviewing (Aurélie Névéol): slideslive, slides
- Just what do you think you’re doing, Dave? A checklist for responsible data use in NLP. https://arxiv.org/abs/2109.06598
NLP tool assistance in peer review
- Kuznetsov et al. (2024) What Can Natural Language Processing Do for Peer Review? https://arxiv.org/abs/2405.06563